
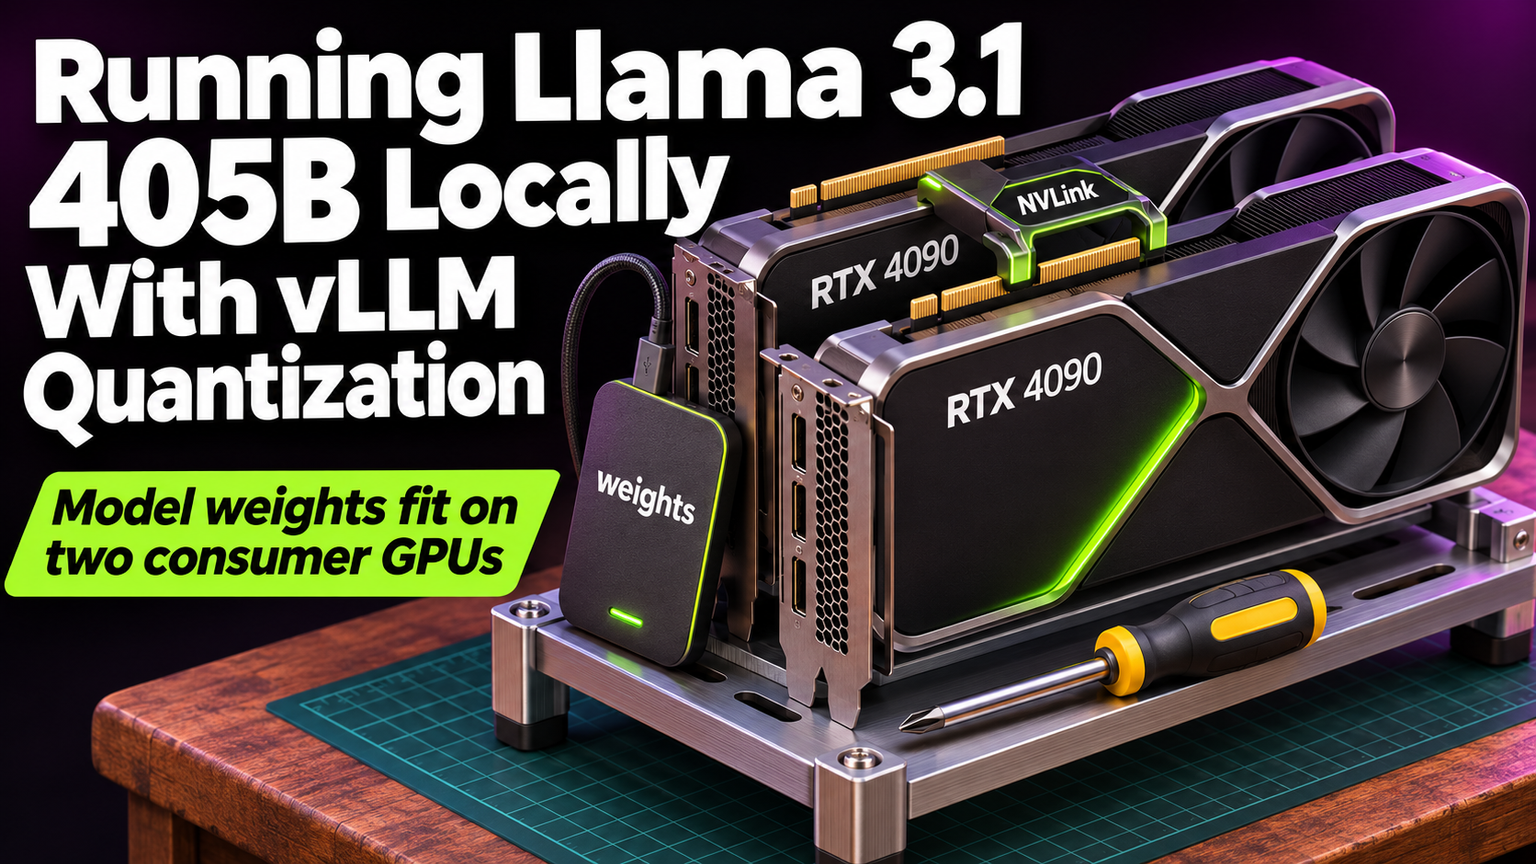
Running Llama 3.1 405B locally isn't a science project anymore — it's a hardware budgeting exercise. At 405 billion parameters, the full-precision model demands roughly 810 GB of VRAM. That's ten H100s. Most teams don't have that. Quantization via vLLM changes the math entirely, dropping requirements to a single 8xH100 node or even dual 48 GB workstations with 4-bit weights.
Why vLLM for 405B?
vLLM's PagedAttention kernel manages KV cache in non-contiguous blocks, eliminating fragmentation. For 405B, this means you can actually fit the model and context window on real hardware. Combined with native FP8 and AWQ support, it's the only inference engine that makes 405B feel responsive instead of glacial.
Hardware Reality Check
| Quantization | VRAM (8x GPU) | Tokens/sec (est.) | Quality Drop |
|---|---|---|---|
| FP16/BF16 | ~810 GB | N/A (OOM) | Baseline |
| FP8 | ~405 GB | 12-18k | Negligible |
| AWQ 4-bit | ~220 GB | 8-12k | ~1-2% MMLU |
| GPTQ 4-bit | ~220 GB | 6-10k | ~1-3% MMLU |
| AWQ 3-bit | ~170 GB | 5-8k | ~3-5% MMLU |
💡
TipFP8 on H100/H200 is the sweet spot — near-lossless quality with 2x throughput. If you're on A100s or consumer GPUs, AWQ 4-bit is your only viable path.
Model Prep: AWQ 4-bit from HF
Don't quantize 405B yourself — it takes days on A100s. Pull pre-quantized weights from Hugging Face. The community standard is casperhansen/llama-3.1-405b-instruct-awq (4-bit, 128 group size). Verify the config matches your vLLM version.
vLLM Launch Config
Tensor parallelism is mandatory. Split across 8 GPUs for FP8, 4-8 for 4-bit depending on VRAM. Pipeline parallelism adds latency — avoid unless you're memory-bound on tensor parallel alone.
⚠️
WarningSet --gpu-memory-utilization 0.93, not 0.95. 405B's KV cache spikes during long contexts will OOM at 0.95. The 64 GB CPU swap space handles overflow gracefully.
FP8 Path (H100 Only)
If you have H100s, skip AWQ. Use the FP8 quantized checkpoint neuralmagic/Meta-Llama-3.1-405B-Instruct-FP8. vLLM detects FP8 automatically — no --quantization flag needed.
Benchmark Before Serving
Run a quick throughput test to validate your parallelism config. Target: >8k tokens/sec aggregate for 4-bit, >12k for FP8.
Production Hardening
Enable prefix caching for repeated system prompts. Use --enable-prefix-caching and structure your chat templates with static prefixes. For multi-tenant, add --max-num-batched-tokens and --max-num-seqs to prevent one request from starving others.
✦
You now have a 405B parameter model serving 8-18k tokens/sec on hardware that costs less than a single H100 node per month. The bottleneck shifted from "can it fit?" to "can you afford the GPUs?" Start with AWQ 4-bit on 4x A100 80GB if budget is tight. Graduate to FP8 on H100 when quality matters. Either way, you're not waiting for API keys anymore.