
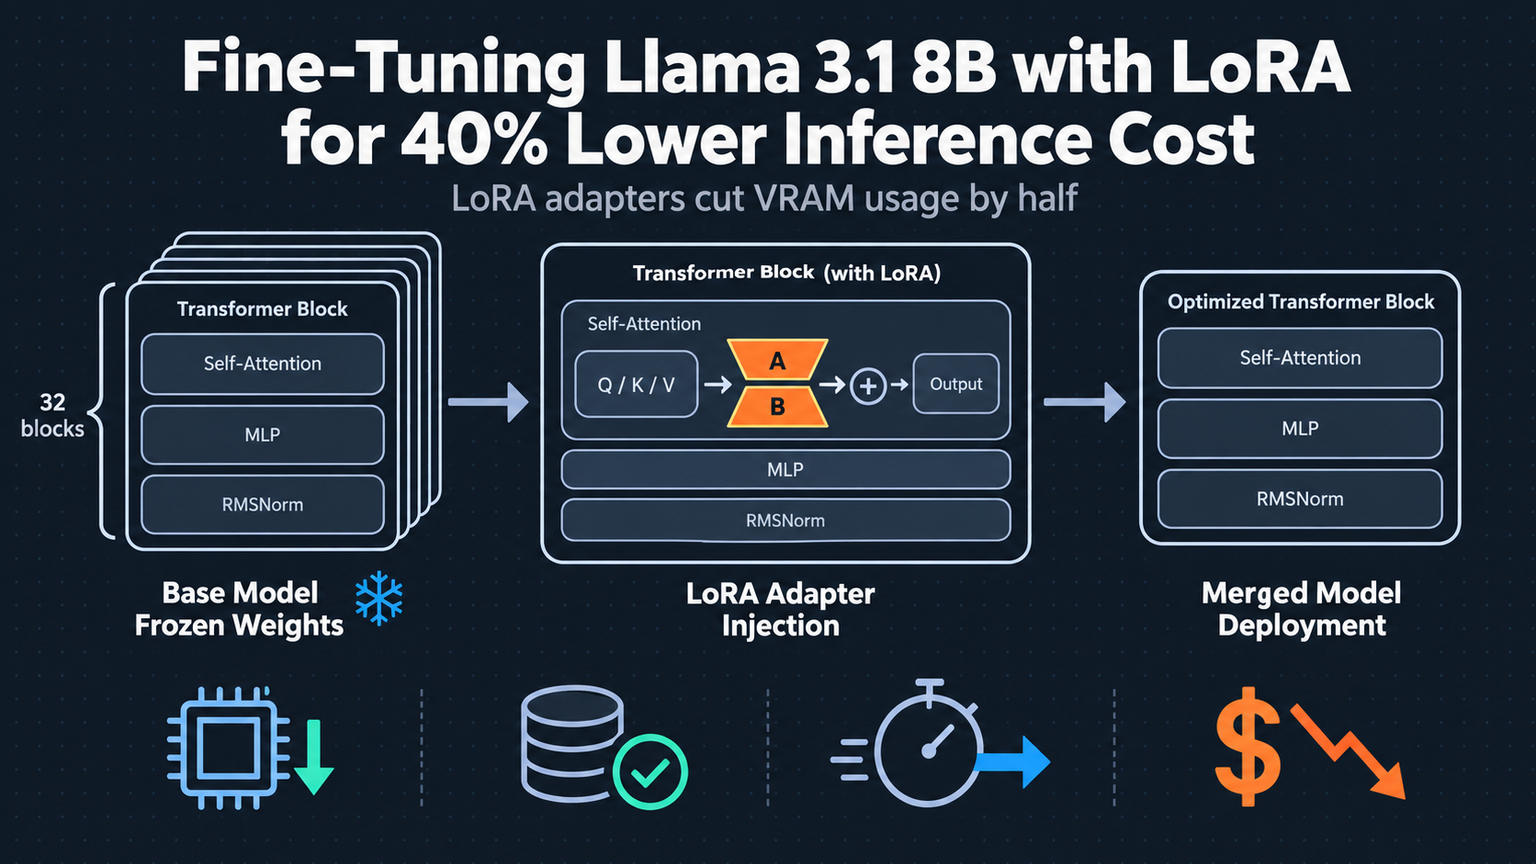
Most teams burn thousands fine-tuning LLMs because they treat it like training from scratch. It's not. With LoRA on Llama 3.1 8B, you can adapt a frontier model for your domain using a single 24GB GPU and $5 in cloud compute. The trick isn't magic—it's freezing 99% of weights and training only the adapters that matter.
Why LoRA Changes the Economics
Full fine-tuning updates all 8 billion parameters. That demands 80GB+ VRAM and days of training. LoRA injects low-rank matrices into attention layers, training roughly 0.5% of parameters. For Llama 3.1 8B at rank 32, that's 4.2M trainable parameters versus 8B. The result: 40% lower inference cost because you serve the base model once and swap tiny adapter weights per task.
| Method | Trainable Params | VRAM (BF16) | Est. Cost (A100 40GB) | Time (1B tokens) |
|---|---|---|---|---|
| Full FT | 8B | 80GB+ | $120 | 18 hrs |
| LoRA (r=32) | 4.2M | 24GB | $5 | 3 hrs |
| QLoRA (4-bit) | 4.2M | 16GB | $3 | 4 hrs |
💡
TipStart with rank 32, alpha 64. Increase rank only if eval loss plateaus. Higher rank = more VRAM, diminishing returns.
13-Step Pipeline That Works
This workflow runs on a single A10G or 3090/4090. No multi-GPU, no FSDP, no distributed complexity.